
How to Choose the Right Machine Learning Model for Your Business
Learn how to approach Machine Learning Model Selection with data readiness, evaluation criteria, and deployment planning built for business results.
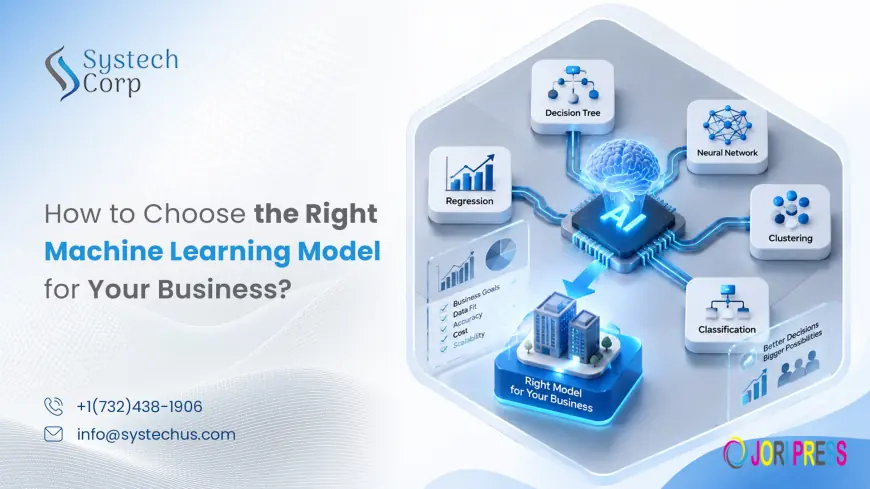
Machine learning model selection becomes challenging when teams overlook the business problem, data requirements, and environment where the model will operate. Machine learning model selection is not a coding exercise but rather a reasoned decision that connects the type of model, the quality of the data, evaluation metrics, and production constraints to measurable outcomes. If models are not carefully selected, businesses ship models that overfit, drift rapidly, and never reach adoption thresholds.
SystechCorp helps businesses take a business-first approach to machine learning model selection, aligning models with specific business objectives, data environments, workflows, and enterprise systems. Through data engineering, feature preparation, model development, deployment, and continuous optimization, SystechCorp helps organizations build scalable machine learning solutions focused on accuracy, reliability, and measurable business outcomes.
This blog explores different types of machine learning models, key selection criteria, evaluation methods, data considerations, and deployment factors businesses should consider when choosing the right model for their specific needs.
What Does Choosing the Right ML Model Really Mean?
Picking the right model means matching an algorithm to what a business actually needs. Balance accuracy, interpretability, latency, scalability, and cost. No model dominates everything.
A fraud engine works differently from a demand forecast. They need different structures. Start with the outcome and constraints. Skip the trendy stuff.
What model selection involves:
-
Algorithm-Outcome Alignment: Match the algorithm to a business outcome first. Then compare accuracy, cost, and complexity. Don't reverse that order.
-
Production Constraint Balance: Interpretability, latency, scalability. Balance these factors against the requirements of the production environment and the needs of end users.
-
Lifecycle Cost Awareness: Maintenance effort matters. Retraining frequency matters. Data governance demands matter. Look at the full lifecycle, not just initial training.
-
Problem-Specific Thinking: One-size-fits-all doesn't work. Every business problem has different data. Risk profiles differ. Your constraints are unique.
How Does Data Quality Influence Machine Learning Model Selection?
Data quality plays a critical role in model selection because data volume, variety, labeling, and completeness influence which algorithms can realistically perform well. Here are the following ways through which data shapes model choice:
-
Labeled Data Advantage: Labeled, supervised learning excels at classification and regression. Predictions are reliable and can be tested for accuracy.
-
Unlabeled Data Strategy: With unlabeled or sparse data, consider clustering and anomaly detection. When labeled data is limited or unavailable, consider unsupervised learning approaches such as clustering and anomaly detection.
-
Feature Engineering Priority: Feature engineering and data governance are more important than changing algorithms. In many cases, improving feature quality can have a greater impact on model performance than simply switching algorithms.
-
Data Readiness First: Poor data harms accuracy. Volume and variety are key. Clean and prepare data before choosing a model.
Which ML Model Type Fits Your Business Problem?
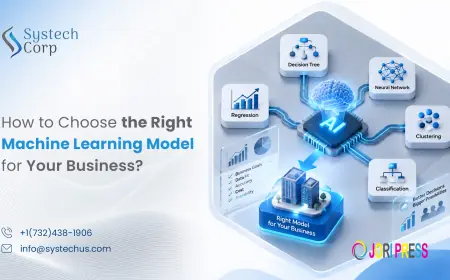
The right model type depends on whether the goal is prediction, grouping, decision-making, or handling unstructured data. Understanding the main types of machine learning models helps teams shortlist candidates fast.
Below, a comparison table maps common business problems to model families and typical applications of machine learning models.
|
Model Family |
Best For |
Business Problem |
Example Applications |
|
Supervised learning |
Prediction, classification |
Labeled outcomes exist |
Credit scoring, churn prediction, demand forecasts |
|
Unsupervised learning |
Segmentation, anomaly detection |
Patterns without labels |
Customer segments, fraud signals |
|
Reinforcement learning |
Dynamic decisions |
Sequential actions and rewards |
Pricing, routing, recommendations |
|
Deep learning |
Unstructured, high-dimensional data |
Images, text, speech |
Computer vision, NLP, document processing |
How Do Accuracy, Interpretability, and Speed Affect Model Selection?
Accuracy, interpretability, and speed are among the most important machine learning model selection criteria, and the highest-accuracy model is rarely the best business fit. Regulated sectors often need explainability over raw performance. Real-time systems need low inference latency. The winning model balances all three against how the business will actually use it.
Balancing core selection criteria
-
Accuracy Limitations: A highly accurate model may not be the right choice if its decisions cannot be explained to regulators, stakeholders, or end users.
-
Explainability Priority: When it comes to use cases in financial services, healthcare, or compliance with audit needs, explainability becomes a top priority.
-
Latency Requirements: Low inference latency maintains fast enough real-time scoring, fraud checks, and recommendations in production.
-
Criteria Trade-Off: Balance accuracy, transparency, and speed with how predictions will be used in day-to-day business operations.
How Can Businesses Compare Machine Learning Models Effectively?
Businesses compare models effectively by testing several candidates against the same objective using consistent evaluation metrics and validation.
Comparing models the right way
-
Classification Metrics: Use precision, recall, F1-score, and ROC-AUC to judge classification model quality against business goals.
-
Regression Metrics: Apply RMSE and MAE for regression models to measure prediction error against real values.
-
Cross-Validation Testing: Test multiple candidates on the same objective using cross-validation and consistent, repeatable benchmarking methods.
-
Error Analysis: Run error analysis to expose weak segments before any model reaches production decisions.
What Deployment and Integration Factors Should Businesses Consider?
Deployment and integration factors decide whether a strong model survives outside the lab. Several deployment factors can determine whether a model performs reliably in a production environment:
-
Infrastructure Fit: Cloud infrastructure, APIs, computing resources, and existing enterprise systems should support the model's deployment, integration, and performance requirements.
-
MLOps Automation: MLOps pipelines automate deployment, versioning, and retraining to ensure models remain reliable at business scale.
-
Drift Detection: Production monitoring can detect model drift early, before accuracy silently slips away and decisions become unreliable.
-
Compute Alignment: Select models based on compute performance and latency requirements, not just experimental accuracy scores.
How Do Industry Use Cases Influence the Right Model Choice?
Industry use cases determine the choice of models since each industry has different data, risks, and compliance requirements. Different industries prioritize different model requirements based on their data, business objectives, risks, and regulatory needs.
-
Finance Applications: Banks focus on fraud detection, credit risk, and compliance monitoring. They use predictive analytics and anomaly detection to spot issues early.
-
Retail and Manufacturing Applications: Retail and manufacturing face unique challenges. Demand forecasting is key. So is inventory management and quality control. Models must address all three.
-
Healthcare Applications: Healthcare is different too. Risk scoring and classification help identify patients needing immediate care. Risk scoring and classification can help healthcare organizations identify high-risk cases and support earlier intervention.
-
Cross-Industry Automation: One common thread connects all industries. NLP and computer vision automate repetitive tasks. Document processing, customer insights, and inspections all speed up with the right model.
What Are the Most Common ML Model Selection Mistakes?
The most common mistakes start with picking tools before defining goals and ignoring data readiness. The following are the common mistakes to avoid when doing ML model selection:
-
Goal-First Approach: Starting with tools instead of business goals leads to models nobody actually needs.
-
Data Readiness Gap: No algorithm choice can make up for the lack of data readiness and governance, which affects accuracy.
-
Complexity Risk: Chasing complexity leads to overfitting, underfitting, and models that are too sensitive for real production.
-
Deployment Planning: Without deployment planning, monitoring, and adoption planning, strong models remain in perpetual experimentation.
How Does SystechCorp Support ML Model Selection and Deployment?
SystechCorp helps businesses identify, develop, deploy, and continuously optimize machine learning models based on their specific business objectives, data environment, and operational requirements. Being an AI & machine learning solutions company, the team matches the choice with business workflows and enterprise systems supported by broader big data and IT consulting strength.
How SystechCorp Helps Businesses Select and Deploy ML Models?
-
End-to-End Delivery: End-to-end delivery includes data engineering, model creation, deployment pipelines, and continuous performance monitoring for reliability.
-
Business-Aligned Selection: Business-aligned selection links each model to actual business workflows, reporting requirements, and enterprise system integration.
-
Continuous Improvement: Continuous improvement addresses retraining and model drift, keeping accuracy intact during changing business conditions.
-
ML Consulting Expertise: Trusted machine learning consulting services in the USA connect model choices to measurable, long-term outcomes.
Business clarity, data readiness, and deployment planning are key factors in strong model selection, whereas technical novelty is not. The importance of model selection is clear in terms of accuracy, adoption, and long-lasting impact. First, define the desired outcome, then review the information, and then make comparisons between models and real metrics before investing.
Ready to turn data into dependable decisions? Partner with SystechCorp for expert Machine Learning Model Selection, model development, deployment, and continuous optimization built for real business growth.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0