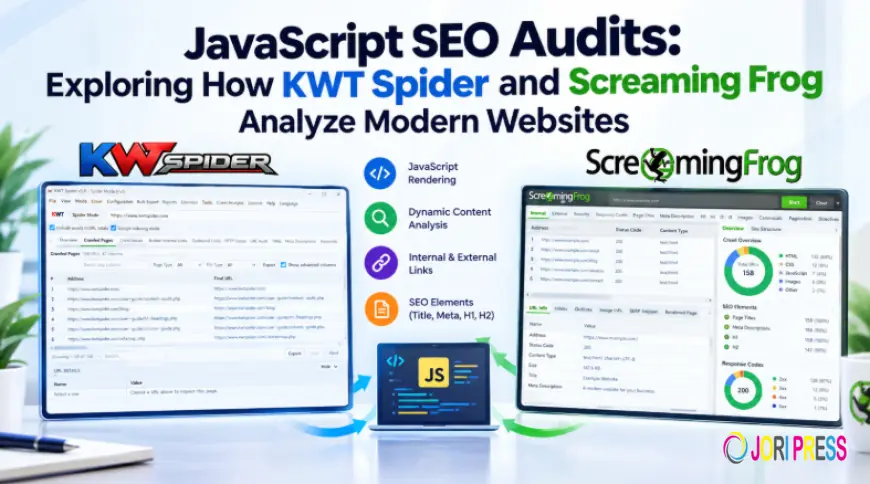
JavaScript SEO Audits: Exploring How KWT Spider and Screaming Frog Analyze Modern Websites
A comprehensive technical guide on JavaScript SEO auditing, comparing how tools like KWT Spider and Screaming Frog analyze original HTML versus fully rendered pages to ensure dynamic content, internal links, metadata, and structured data remain accessible to search engines. Learn how to conduct JavaScript SEO audits using KWT Spider and Screaming Frog. Discover best practices for analyzing rendered pages, dynamic content, and site architecture.
Think of a page that starts with a basic HTML app shell, where JavaScript then loads the navigation links, product description, and additional content. JavaScript frameworks, client-side rendering, dynamic content, interactive elements, and application-style interfaces are now common across websites of all sizes.
That evolution has also changed the way SEO professionals audit websites.
A page may appear complete when viewed in a browser while its underlying HTML, links, metadata, or content behave differently when processed by a crawler. This makes JavaScript SEO an important part of technical website auditing.
Tools such as KWT Spider and Screaming Frog can help SEO professionals investigate how modern websites behave during crawling. While their workflows may differ, both can provide useful information for understanding technical issues that are not always obvious from a normal browser visit.
What Is JavaScript SEO?
JavaScript SEO is the process of ensuring that a website’s important content and functionality remains accessible to search engines and other automated systems when JavaScript is present. With JavaScript you can:
• Dynamic content display
• Link building
• Render navigation menus
• Show product details
• Create filters and interactive parts
• Import metadata/structured data
• Design full page interfaces
• Data from APIs
These techniques are useful for modern web design but can bring SEO considerations. For example, a website might serve a relatively small HTML document first, and then use JavaScript to populate the main content later. If the important information or links are only available after rendering then SEO audits need to consider how they are discovered and processed.
Why JavaScript is Important in an SEO Audit
The traditional crawl will often start by fetching the html that the server sends back. This HTML can display important information such as:
• HTML tags
• Meta tag descriptions
• Canonical URL
• Headers
• Internal links
• Photographs
• Status-codes
• Organized data
• Home page contents
But JavaScript can modify what gets displayed on the page. Therefore, a JavaScript heavy website may need more detailed investigation than a static HTML website. SEOs might want to compare the original HTML with the rendered page to see if important elements are being added, removed or modified by JavaScript.
The Difference Between HTML Crawling vs. Rendering
One of the most important concepts in JavaScript SEO is the difference between crawling the original HTML of a page and the rendered version of the page. Consider a page where the initial HTML contains a basic application shell. JavaScript then loads the product description, navigation links, and other content A simple HTML crawl might see only part of the page. The rendering process can give a different view by allowing JavaScript to run and see what's available afterward. This distinction can be useful in identifying issues such as:
• JavaScript only rendered content
• Links created dynamically
• No metadata
• Modifications to canonical elements
• Client side redirection
• Content that does not appear
• Rendering based navigation
Learning about both versions can give you a much clearer picture of how a modern website works.
How KWT Spider Works for JavaScript SEO Audits
KWT Spider can be used as part of a technical SEO workflow to analyze modern websites and find problems with page structure, links, content and crawlability. Its desktop-based approach is especially helpful for teams who want to crawl websites locally. For JavaScript-heavy sites, an SEO pro can use crawl findings to dig into how pages are structured and to check if important resources, links and content are accessible during the audit. This is particularly helpful when JavaScript is used in conjunction with other technical factors such as:
• Large scale web architectures
• Navigation with dynamic
• Complex internal linking
• Various page templates
• Data structures
• AI Search Preparedness
• Large amounts of URLs. The broader technical analysis of KWT Spider can thus be framed with JavaScript specific checks, rather than treating JavaScript as a separate issue.
How Screaming Frog Helps with JavaScript SEO
Screaming Frog is a long-standing tool for technical SEO crawling and has functionality for auditing JavaScript-reliant sites too. Its JavaScript rendering features can allow SEO pros to see what a page looks like after rendering, not just the original HTML response. This is useful when auditing websites built with modern frameworks, or pages where important elements are dynamically generated. For example, an SEO professional may use a crawl to check if:
• Internal links are rendered after rendering
• Content is available in rendered HTML
• Changes to the metadata during rendering
• JavaScript written elements
• Pages return expected content
• Rendering involves technical differences
This means that JavaScript rendering becomes a handy part of a broader technical SEO audit.
JavaScript Websites Audit: What to Look For
It doesn’t matter what type of crawler; the audits should be focused on the elements that matter for search accessibility and website structure.
1. Relevant content
Determine whether the main content is present in the original HTML or if it is heavily dependent on JavaScript. If critical content is only available after rendering, it deserves a closer look. This doesn’t necessarily mean there is an SEO problem with the page, but it is an important detail in the architecture.
2. Internal Links
Internal links are especially important on JavaScript-heavy websites. A navigation system may appear complete in a browser, but may rely on JavaScript events or other mechanisms that do not behave like traditional crawlable links. An audit should look at whether important internal URLs can be found properly.
3. Metadata
JavaScript can sometimes affect titles, descriptions, canonical tags, robots directives and other metadata. Compare the initial HTML with the rendered page (if applicable) to verify significant metadata changes.
4. Data Tables
You can also use JavaScript to produce structured data. SEO teams should check that structured data is available in the expected format and that it accurately represents the page. While structured data isn’t a guarantee of search visibility, incorrect or inconsistent implementation can lead to technical issues worth investigating.
5. Status Codes and Redirects
Sometimes client-side navigation or redirects are handled by JavaScript. These should be reviewed closely since a technically working browser experience does not necessarily mean the implementation is ideal from a crawling standpoint.
JavaScript SEO and Large Sites
As sites are growing, JavaScript considerations are even more important. An ecommerce website, publisher, SaaS platform, or large corporate site may have thousands or millions of URLs generated through templates and application logic. Hence, a small problem with the implementation can affect many pages. For example, if a template fails to expose important internal links properly, the problem may be repeated throughout an entire section of the website. This is where crawlers come in. They allow SEO teams to detect trends, rather than having to manually review pages one by one. In big audits, KWT Spider’s desktop and local-processing approach can be handy when teams want crawl data to be processed on their machines, and Screaming Frog offers a robust desktop crawling workflow for detailed technical investigations. Which one is right depends on the site architecture, audit requirements and the preferred workflow of the team.
JavaScript SEO Isn't Just About Rendering
It's tempting to think of JavaScript SEO in terms of whether a crawler can render a page. The bigger question is whether:
Does JavaScript change the accessibility, structure, findability or meaning of important content on your site? Even a correctly displayed page can have other technical issues.
For example, it may be fine to render while:
• Important pages have poor internal links
• Canonical URLs are not consistent
• Incorrect metadata
• Navigation creates unnecessary URL variations
• Poor loading of content
• Generates large numbers of URLs
• Structured data errors
JavaScript should therefore be considered in the wider context of technical SEO.
JavaScript Analysis & SEO Audits
The most effective comprehensive JavaScript SEO audit is most often combined with other technical audits. An SEO pro can start with a crawl and then move into areas such as:
Crawlability: Are important URLs discoverable and crawlable?
Indexability: Are your important pages being indexed?
Internal linking: Do you have important pages linked together with useful internal links?
Content: Does content have meaning for automated systems?
Metadata: Are titles, canonicals and other directives correct?
Structured data: Is the structured data implemented correctly?
Performance: Is there too much loading or rendering overhead in the implementation?
Architecture: Does the JavaScript framework introduce unnecessary complexity in URLs or navigation?
With this bigger view, JavaScript is more than just a technical tick box.
KWT Spider and Screaming Frog in a Contemporary SEO Workflow
Both can be used in modern JavaScript SEO audits.
KWT Spider incorporates its desktop crawling workflow into wider technical analysis and modern SEO concerns, and is a choice for teams that want to look at JavaScript-related issues as well as the broader structure of a site.
Screaming Frog is a tried and tested technical SEO crawler with JavaScript rendering capabilities, useful for inspecting dynamically generated material and page elements.
Neither method removes the need for manual investigation. Crawl data can reveal trends and potential problems. Then developers and SEO experts may look at the underlying implementation to see if a change is even necessary.
Conclusion
JavaScript has transformed the way that many websites are built, which means SEO audits also need to look beyond the initial HTML response. A modern JavaScript SEO audit must look at what content, links, metadata and structured data exists before and after rendering, and the broader technical architecture of the website.
KWT Spider and Screaming Frog offer different yet helpful approaches to this process. Screaming Frog is already established for crawling and rendering for technical investigations, but KWT Spider can bring JavaScript-related findings into a wider desktop SEO workflow.
The point, at the end of the day, is not to know whether a website is using JavaScript or not. The goal is to understand what JavaScript changes, if those changes affect search accessibility, and where the implementation can be improved.
For modern websites, that means JavaScript SEO is an important part of a complete technical audit, not a stand-alone task that happens only when something goes wrong.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0