
How AI Agents Handle Errors and Unexpected Situations
Explore how AI agents respond to errors, manage unexpected outcomes, and recover from failures. Discover the techniques that help AI agents adapt, make better decisions, and complete tasks more reliably.
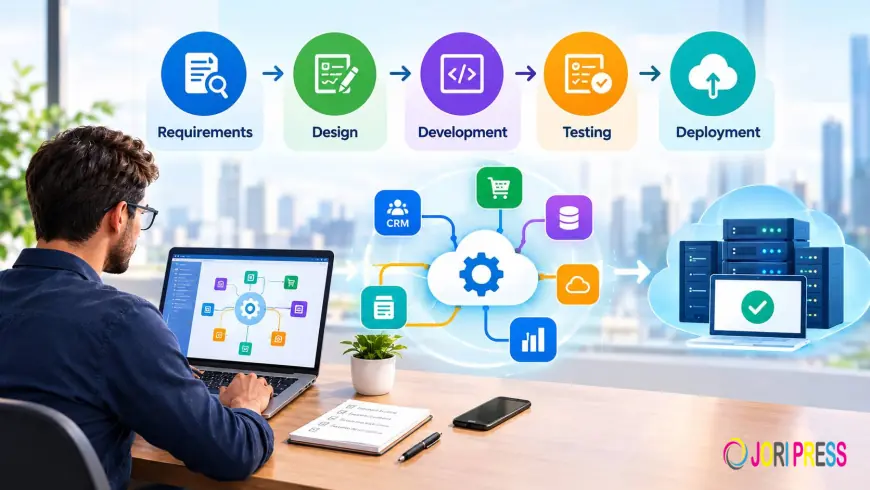
An AI agent that works perfectly in a demo can fall apart the first time a website changes its layout, an API returns garbage, or a customer asks for something nobody planned for.
Handling errors is what separates a prototype from something you can trust with real work. This article explains how agents detect problems, what they do about them, and where human judgment still has to step in.
Why Agents Fail Differently Than Ordinary Software
Traditional software fails in predictable ways. A function receives bad input, throws an exception, and a developer who anticipated that exception has written code to catch it. The failure modes are finite and mostly known in advance.
AI agents work differently because they chain together decisions. A typical agent reads a goal, decides which tool to call, interprets the result, and picks the next step. An error at any point can be silent.
A language model might misread a tool’s output, confidently pass a wrong value downstream, and produce a final answer that looks fine but rests on a bad foundation. A crashed program is easy to notice. An agent that quietly goes wrong is much harder to catch.
That is why error handling for agents has to cover two separate problems: failures the system can see (timeouts, error codes, malformed data) and failures it cannot see directly (wrong reasoning, misunderstood instructions, outdated assumptions).
The Common Types of Errors Agents Encounter
Most problems fall into a handful of categories, and each calls for a different response.
- Tool and API failures. A service times out, returns a rate-limit message, or sends back a response in a format the agent did not expect. These are the most visible errors and the easiest to handle with conventional engineering.
- Bad or ambiguous input. A user gives an incomplete instruction, or a document contains contradictory information. The agent has to decide whether to guess, ask, or stop.
- Environment changes. A web page is redesigned, a file is moved, or a database schema is updated. The agent’s plan was sound yesterday and is wrong today.
- Reasoning errors. The model draws an incorrect conclusion, misreads a number, or invents a detail that does not exist. This category is the hardest because nothing technically “breaks.”
- Goal drift. Over a long task, the agent gradually loses track of the original objective and starts optimizing for something adjacent to it.
Retries, Backoff, and Fallbacks
For transient problems, the first line of defense is borrowed directly from distributed systems engineering. If a request fails, try again, but not instantly and not forever.
Retrying with exponential backoff means waiting a little longer after each failed attempt, which gives an overloaded service room to recover instead of hammering it. A cap on the number of attempts matters just as much. An agent without a retry limit can burn through time and API budget repeating a request that will never succeed.
When retries are exhausted, a well-designed agent moves to a fallback. That might be a secondary data source, a simpler method of accomplishing the same step, or a cached result clearly labeled as possibly out of date.
The key design choice is making the fallback visible. If an agent substitutes older data without saying so, the person reading the output has no way to judge how much to trust it.
Self-Checking and Verification Loops
Retries handle the failures an agent can see. Verification handles the ones it cannot.
Many production agents include a checking step after an action. After writing code, the agent runs the tests. After extracting figures from a report, it recalculates the totals and compares them. After filling in a form, it reads the page back to confirm the values were saved.
The principle is simple: do not treat an action as successful just because it did not raise an error. Some systems add a second pass in which the model critiques its own output against the original request, or a separate model reviews the first one’s work. This helps, but it is not foolproof.
A model reviewing its own reasoning can repeat the same mistake, so checks that rely on something external, such as a test suite, a schema validator, or a known reference value, are more dependable than checks that rely on the model’s opinion of itself.
A Worked Example: A Content Agent for a Local Service Business
Consider a small mortgage brokerage that uses an agent to maintain its website and respond to routine inquiries. Suppose the agent is asked to update the local pages for each area the firm serves, such as a page for Professional Mortgage Advice in Rainham, and to check that each page still loads and displays the correct contact details.
Several things can go wrong here. The site’s content management system might time out during a bulk update, which is a transient failure handled with a retry. A page might save successfully but with a broken template, which only a verification step (loading the page and checking for the expected phone number) would catch.
The agent might encounter an instruction it cannot safely act on, such as a request to state a specific interest rate on a page, where the correct answer depends on the lender and the applicant’s circumstances. A sensible agent does not guess. It flags the request and routes it to a person.
The same pattern applies to any business that delegates routine tasks. Retry what is transient, verify what is important, and escalate what involves judgment or risk.
Knowing When to Stop and Ask
The most underrated skill in an agent is knowing when it should not continue. A system that always pushes forward to produce an answer will occasionally produce a confident wrong one.
Good agents have defined escalation points. These are conditions under which the agent pauses and hands control to a human: an action that cannot be undone, a request outside its permissions, repeated failures on the same step, or low confidence in an interpretation. Deleting records, sending payments, and emailing customers are typical examples of actions that deserve a confirmation step rather than autonomous execution.
There is a real tradeoff here. An agent that asks for confirmation constantly becomes tiresome and defeats the purpose of automation. One that never asks takes on risk the organization may not want. The right balance depends on the cost of a mistake. Drafting an internal summary can be fully automatic. Publishing to a customer-facing page might need review. Anything touching money or legal commitments usually warrants a human decision.
Guardrails, Permissions, and Limits
Not every error should be anticipated individually. A more reliable approach is to limit the damage any single failure can cause.
That means giving the agent only the permissions it needs, setting hard caps on spending, runtime, and the number of tool calls, and running risky actions in a sandbox where mistakes can be rolled back. If an agent can only read from a database, a reasoning error cannot corrupt it. If a task has a time limit, a loop cannot run for hours.
These constraints work regardless of how the model behaves, which is exactly why they are valuable. Instructions in a prompt such as “be careful” are helpful but not enforceable. A permission boundary is.
Logging, Monitoring, and Learning From Failures
Handling an error well in the moment is only half the job. The other half is making sure someone learns from it.
Detailed logs of what the agent decided, which tools it called, what came back, and why it chose its next step make it possible to diagnose problems after the fact. Without that trail, a failure turns into guesswork.
Teams that run agents seriously tend to review failed and borderline runs regularly, looking for patterns: a tool that fails more than expected, an instruction that is repeatedly misunderstood, or a task type that should always require approval.
This is also where content and operations teams can benefit. A business that documents how its processes work, which is the same discipline behind Blogging to Generate Leads through clear, consistent published material, gives an agent better context to work from.
Clear source material reduces ambiguity, and less ambiguity means fewer unexpected situations in the first place.
Designing for the Unexpected
Some situations will always fall outside what anyone planned for. The goal is not to eliminate surprises but to make sure the agent responds to them safely.
A few design habits help. Write tasks with clear success criteria so the agent can tell whether it finished. Make failure an acceptable outcome: an agent that is allowed to say “I could not complete this step” is far more useful than one pressured to always return something.
Test with messy, realistic inputs rather than only clean examples. And keep a person in the loop for decisions where the consequences are hard to reverse.
Local businesses face a version of this too. A firm offering a Mortgage Broker in Brentwood service might automate appointment requests and routine questions, but a sensible setup still hands anything involving advice, eligibility, or a specific financial recommendation to a qualified person. The agent handles the routine work, and people handle the cases where individual circumstances decide the answer.
What to Do Next
If you are building or evaluating an agent, start by listing the three or four ways it is most likely to fail and deciding in advance what should happen in each case: retry, fall back, or ask a person. Add one external verification step to the most important task. Then set clear limits on permissions and spending before the agent touches anything that matters. Those three steps will prevent most of the problems that catch teams off guard.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
1